
Take a look at the comic below, a classic false-belief test. Modern large language models now pass it, that is, they correctly infer that when the boy in blue comes back he will look for the cat in the basket, because he “did not see” his friend move it into the box. It is fascinating: a system trained purely on text can emergently model other people’s mental states and work with the perception of time and the sequence of events. It looks like a breakthrough.
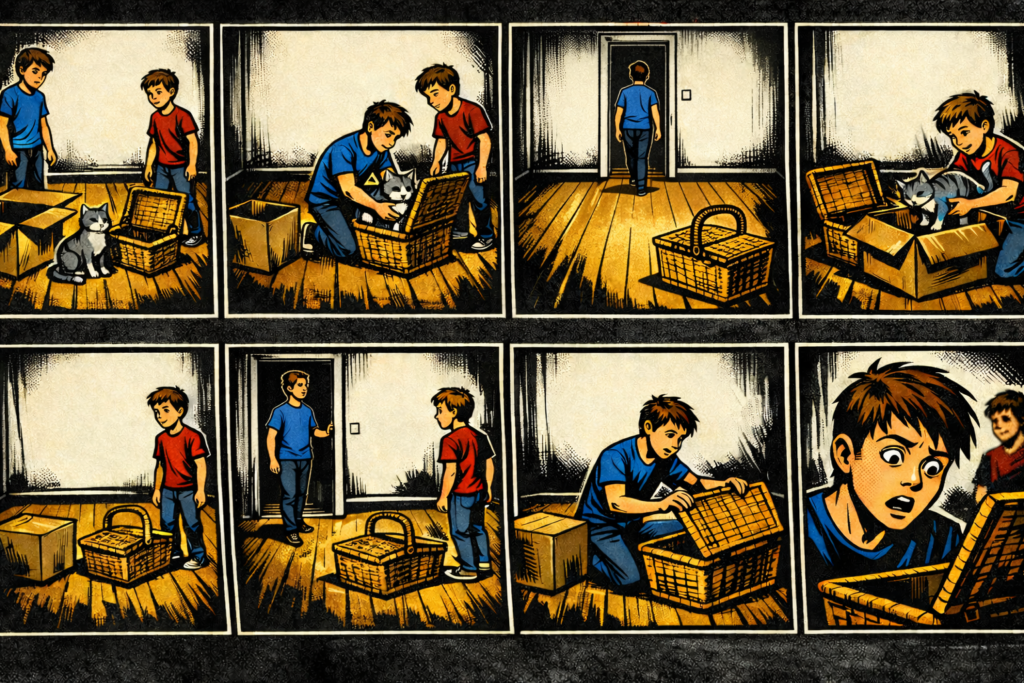
And yet I lean towards Yann LeCun’s position that this is not yet genuine understanding of the world, and that scaling LLMs on its own will not get us to AGI. Let me explain why.
An LLM learns from hundreds of billions of words about the world, but it has never experienced the world. When a model “knows” that a hot mug burns, it is because it has read millions of sentences about hot mugs and burns. It can even connect that with information from a medical study or the leaflet of a burn treatment. Except that when a child grasps that a hot mug burns, it is because it once touched something hot and felt pain. It did not have to read a single sentence about it. That difference is not trivial. It is a fundamentally different quality and route of knowing.
Consider the concrete limits of describing reality in words. You can describe physical pain with a thousand metaphors, “like being stabbed with a knife”, “it burns like fire”, “a dull throbbing”, but nobody who has never felt pain will truly understand it from those words. The same goes for the taste of blue cheese, the feeling of exhaustion after a marathon, or the experience of a Leonard Cohen concert. There is an unbridgeable gulf between “knowing that sunsets tend to be orange” and actually seeing that glowing orange in the sky.
Spatial relationships are another problem area. You can write “a sphere 10 cm in diameter fits into a box measuring 15x15x15 cm”, but really understanding how such a sphere behaves, how it rolls down an inclined plane, how you grip it in different ways, how it looks from different angles, perspectives and distances, calls for a geometric and sensorimotor intuition that does not always follow directly from words. An LLM can answer questions about geometry correctly, but it cannot genuinely imagine how an object would behave in space, because it lacks embodied experience of a three-dimensional world.
Causality is an even deeper problem. Text describes causal relationships with words like “caused”, “led to”, “followed from”. But real understanding of causality comes from active interaction with the world: you push things and they move, you heat water and it boils, you drop a ball and it falls. That active exploration builds a deep intuitive grasp that particular actions have particular consequences, and it is fundamentally different from merely reading about those relationships. A child who has dropped a toy a hundred times and watched it fall has a different understanding of gravity than a system that has read a million sentences about falling objects.
So when an LLM learns to recognise a false belief in a comic strip, that is an impressive statistical ability, but it is not the same as the genuine understanding of mental states that we have. We are beings who have not only read about other minds but have personally experienced a thousand times over that another person does not know what we know, because they were not there. Our model of other minds is anchored in our own experience as creatures with a limited perspective, in our own errors and surprises, not merely in textual patterns about those limits.
LeCun is right when he says we need world models, not just language models. His Joint Embedding Predictive Architecture tries to capture how the world evolves over time: not predicting the next word, but predicting the next state of reality in an abstract representational space. That is fundamentally closer to the way animals and humans understand the world, by constantly forming expectations about what will happen and learning from the surprise when reality turns out differently.
His energy-based models represent a different epistemology. Instead of “what is probable given the statistics of text” they ask “what is consistent with physical reality”. The difference matters: an LLM can generate fluent text about water flowing uphill if that is statistically conditioned by the preceding context. An energy-based model grounded in observation of the world ought to reject such a scenario, because it violates physical consistency.
So why are language models not the road to AGI? Because true general intelligence requires the ability to operate in reality, not just to talk about it. AGI has to be able to plan in an uncertain world, anticipate the physical consequences of actions, learn from interaction and devise new strategies for new situations. All of that requires an internal model of how the world works, a model verified by active testing rather than merely assembled from textual patterns.
This does not mean LLMs are worthless. They are economically transformative and useful for a great many tasks. But mistaking the ability to speak fluently about the world for the ability to genuinely understand it is a category error. It is the same mistake as thinking that someone who has read every book about swimming can swim.
The future, in my view, lies where LeCun has long been pointing: in systems that learn from the world itself, from video, from sensory data, from robotic interaction, from a constant cycle of prediction and surprise. Systems that do not merely talk about gravity but “feel” it in their predictions of how objects move. Systems that do not merely recite sentences about heat and cold but hold an internal representation of those properties grounded in observed physical processes.
LeCun held this position almost alone for nearly ten years and was often dismissed for it as “the old grouch from the convolutional-network era”. Now, though, the picture is changing. Ilya Sutskever, co-founder of OpenAI and one of the chief architects of the scaling era, recently admitted on Dwarkesh Patel’s podcast that scaling alone will not get us to AGI and that “something essential is missing”. All of a sudden it is not just “the grumbling of an AI dinosaur”.
The trouble is that LeCun’s energy-based models and JEPA are technically elegant but not yet practically usable at the scale transformers are. And the market does not care about “maybe one day”; it cares about the present.
Sources:
- https://saanyaojha.substack.com/p/the-man-who-cant-be-moved
- https://ai.meta.com/vjepa/
- https://youtu.be/PqVbypvxDto?si=nCCZIQ3llFcv04lw
- https://www.linkedin.com/posts/ravid-shwartz-ziv-8bb18761_heres-a-simple-rule-i-use-when-someone-ugcPost-7406818476725526531-0EQo
- https://x.com/ylecun/status/2003227257587007712?s=46


